
- 세상의 모든 계산기 자유(질문) 게시판 일반 ()
알파고 2.0 ??
-

- 2022.12.02 - 12:36 2017.05.25 - 21:40 9864 13
1. 경향신문 기사 中
작년 3월 이세돌 대국 당시 알파고는 구글이 개발한 AI용 칩인 ‘TPU’ 50개를 동원하는 등 대규모 전산 설비를 썼지만, 올해에는 TPU 4개를 얹은 산업용 컴퓨터(machine) 1대만 썼다.
원문보기:
http://news.khan.co.kr/kh_news/khan_art_view.html?artid=201705251847001&code=970204&nv=stand&utm_source=naver&utm_medium=newsstand&utm_campaign=row1_4#csidx014b2a168e8fece83d99057dbfba69d

2. 블로터 기사 中
이세돌 9단과 대국한 알파고는 구글 클라우드 상 50개의 TPU(Tensor Processing Unit)를 사용했다. TPU는 구글이 머신러닝을 위해 특별히 제작한 처리장치다. 1초에 50개의 수와 10만개의 형태를 탐색할 수 있었다. 현재 커제 9단과 대국 중인 알파고는 ‘알파고 마스터’라고 불리는 버전이다. 이번 구글 I/O 에서 공개된 단일 TPU 머신을 사용하며 2016년 버전 대비 10분의 1의 컴퓨팅 파워를 사용하면서도 더 빨리 계산한다.
http://www.bloter.net/archives/280664
3. NEXTPLATFORM - TPU2에 대한 기사 中
Google’s first generation TPU consumed 40 watts at load while performing 16-bit integer matrix multiplies at a rate of 23 TOPS. Google doubled that operational speed to 45 TFLOPS for TPU2 while increasing the computational complexity by upgrading to 16-bit floating point operations. A rough rule of thumb says that is at least two doublings of power consumption – TPU2 must consume at least 160 watts if it does nothing else other than double the speed and move to FP16. The heat sink size hints at much higher power consumption, somewhere above 200 watts.
https://www.nextplatform.com/2017/05/22/hood-googles-tpu2-machine-learning-clusters/
-
25
댓글13
-
세상의모든계산기
In-Datacenter Performance Analysis of a Tensor Processing Unit ™
https://drive.google.com/file/d/0Bx4hafXDDq2EMzRNcy1vSUxtcEk/view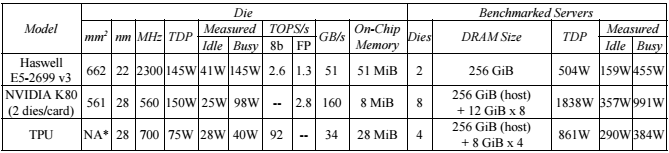
※ 이 논문은 TPU2 가 아닌 TPU(1세대) 을 대상으로 작성된 논문입니다.
-
세상의모든계산기
NVIDIA V100
출처 : https://devblogs.nvidia.com/parallelforall/inside-volta/?ncid=so-fac-vt-13920
Tesla V100 delivers industry-leading floating-point and integer performance. Peak computation rates (based on GPU Boost clock rate) are:
7.5 TFLOP/s of double precision floating-point (FP64) performance;
15 TFLOP/s of single precision (FP32) performance;
120 Tensor TFLOP/s of mixed-precision matrix-multiply-and-accumulate.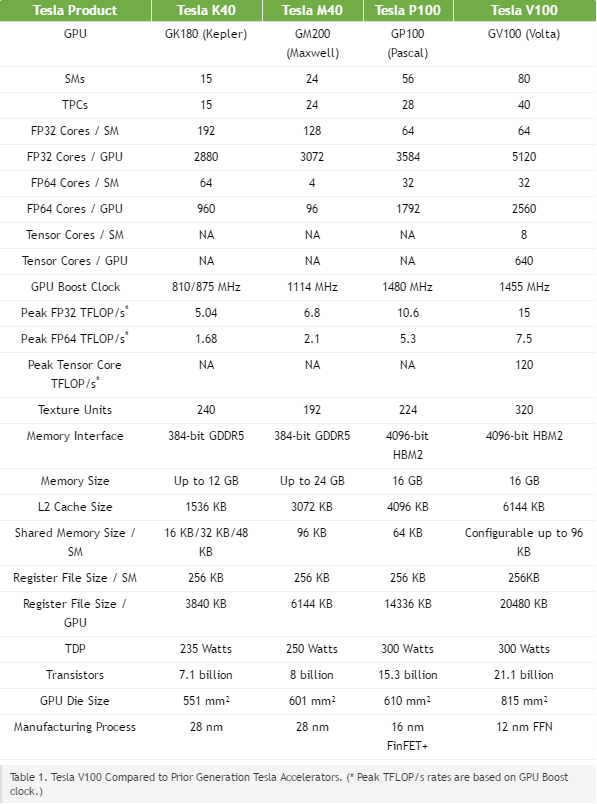
-
세상의모든계산기
팩트 정리를 해 보면...
1. 돌파고의 TPU는 TPU1 으로 불림2. 커파고의 TPU는 TPU2 로 불림
(칩을 TPU2 Chip 으로 부르기도 하는 듯)3. TPU2 모듈 1개는 TPU2코어 4개로 구성
4. TPU2 모듈의 성능 = 45테라플롭스/개*4개 = 180테라플롭스 (
5. https://www.tensorflow.org/tfrc/ 구글 텐서 크라우드?는 100개의 TPU2 모듈로 구성
각각의 TPU2 칩은 두개의 BlueLink 25GB/s 케이블로 연결 -
세상의모든계산기
추정
CPU 종류와 그 비율
출처 : https://www.nextplatform.com/2017/05/22/hood-googles-tpu2-machine-learning-clusters/
We believe that Google connected each CPU board to exactly one TPU2 board using both OPA cables to achieve 25 GB/s aggregate bandwidth. This one-to-one connectivity answers a key question for TPU2 – Google designed the TPU2 stamp with a 2:1 ratio of TPU2 chips to Xeon sockets. That is, four TPU2 chips for every dual-socket Xeon server.> 클라우드가 아닌 싱글머쉰에서 알파고가 돌아갔다면 제온 2소켓 보드 + TPU2 모듈*1개 구성이 맞는 듯
> CPU는 구글 문서에 나온대로 INTEL XEON E5-2699v3 인것 같음. 실질적 계산 역할은 그리 크지 않은 듯.
(seldom 하게 2.3GHz 이외 클럭으로 동작)> 전력소모는 구글 문서에 나온대로 TDP 861W, IDLE 290W, BUSY 384W (싱글머쉰 기준) 이 맞는 듯

세상의모든계산기 님의 최근 댓글
https://v.daum.net/v/20261116194430905 [단독]로봇고 출신 세무사 수석, ‘개조 계산기’로 AI 답안 받은듯 본문은 2017년 글이니, 9년간 계획을 실행에 옮겼을 리는 없고...? 34세? 설마 아니겠지?? 2026 11.16 https://v.daum.net/v/20261115103924120 2026 11.15 언제 추가되었는지 확인은 못하였습니다만, 델리(DELI) D991EX 가 허용군에 추가되어 본문 갱신하였습니다 2026 11.10 좋은 정보 감사드립니다. 링크 글은 수정하였습니다. 2026 11.10 게임에서는 왜 굳이 버림을 쓸까요? 반올림이면 이런 일이 생깁니다. 진짜 99.99996% → 반올림하면 표시 100.0000% 눈에는 100%인데 렙업이 안 된 거죠. 이건 플레이어 입장에서 명백한 버그로 보입니다. 버림이면 표시가 진짜를 절대 초과하지 않습니다. 진짜 99.99996% → 표시 99.9999% 진짜 100.00000% → 표시 100.0000% = 딱 렙업 즉, 표시가 100%가 되는 순간 = 진짜로 렙업되는 순간이 일치합니다. 2026 11.08